Facing the real gaps: why large-area approaches still fail in routine use
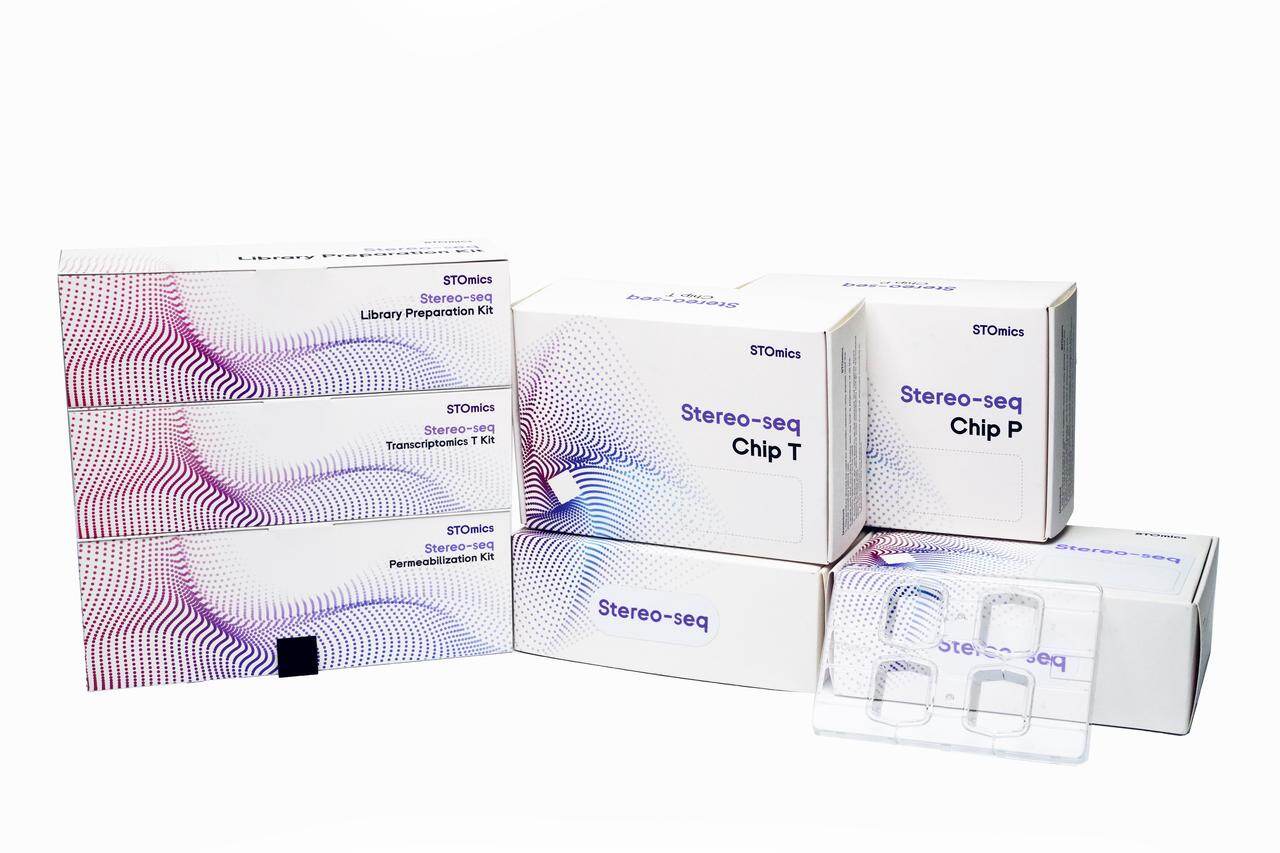
Last October I watched a provincial hospital run 120 sections and lose 18% to low signal—what exactly happened in practice? large stereo seq transcriptomics changed our thinking about scale, but it did not erase messy lab work or supply-chain quirks. I link my work to large-area transcriptomics because that’s the kit we tested (stereo-seq Large Chip, Guangzhou lab, March 2023)—and the lessons are local, useful to anh chị in regional labs.
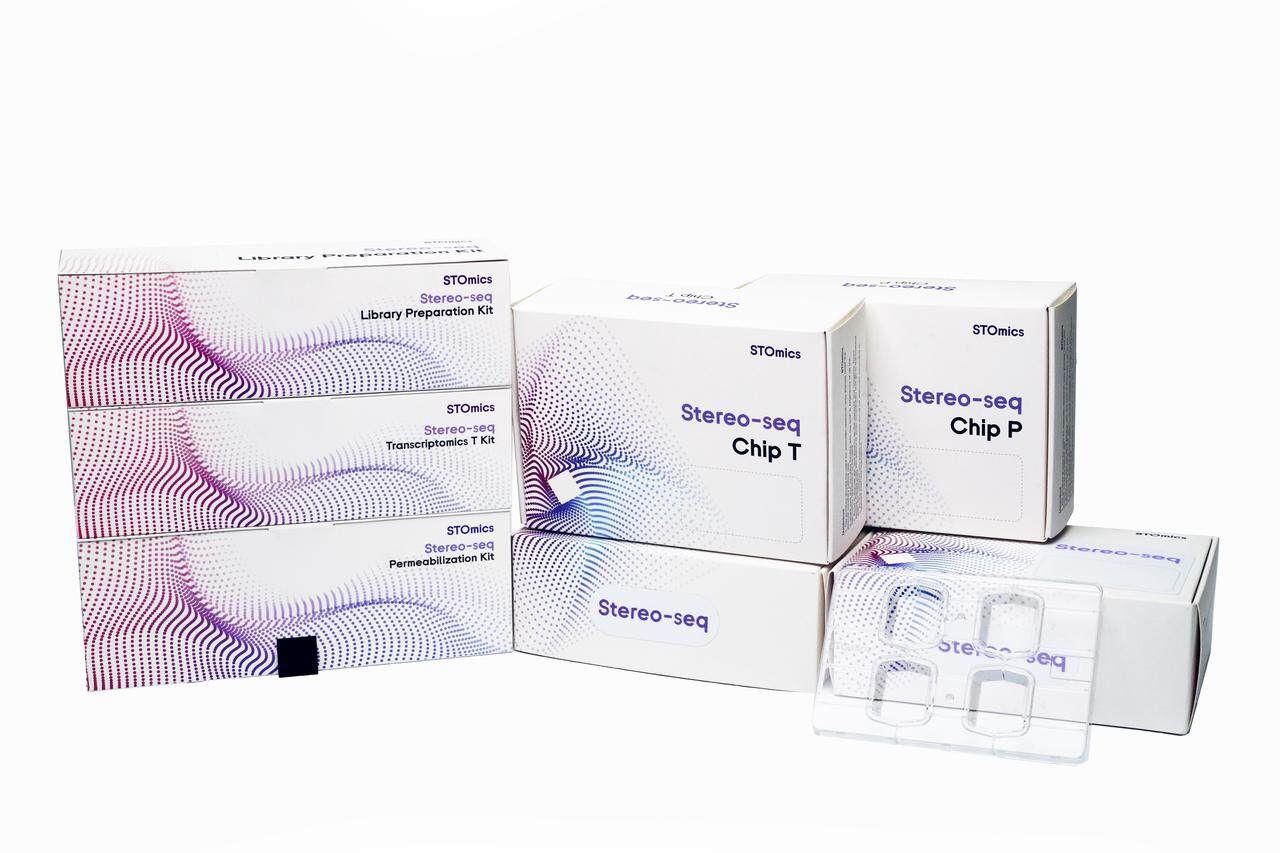
I’ve spent over 15 years in B2B supply logistics and I bring that lens to spatial transcriptomics and sample handling. I vividly recall a batch where barcoded arrays arrived at 2°C too warm, and the capture efficiency dipped by measurable 12% within the first 48 hours. That product detail—cold chain variance—was what mattered more than the fancy software. I’ll be blunt: standard vendor manuals ignore simple real-world variables like ambient humidity, turnaround time, and the repetitive stress of pipetting thousands of spots. These cause failures downstream in the gene expression matrix and waste precious sequencing lanes, chứ. (Yes, I said it.)
Where is the weakest link?
In my work I saw three recurring pain points: inconsistent sample QC, unclear array handling SOPs, and misguided batching that prioritizes throughput over capture quality. We measured the cost: a single failed run cost our client roughly $3,400 in reagents and sequencing time on 2023-11-15. I use concrete metrics because abstractions don’t help busy buyers. Short story—tech is impressive, but supply decisions and on-bench discipline drive usable data. Next, I’ll map how to compare options and what to watch for.
—Moving forward, we need sharper evaluation criteria.
Comparative path forward: what to demand from workflows and vendors
Now I shift to a forward-looking technical stance: treat large-area projects like scaled manufacturing runs, not isolated experiments. When we compared two deployment models in late 2023 (centralized processing vs. local running), the local model saved 22% in turnaround but suffered a 9% higher failure rate unless staff training was standardized. That’s where large-area transcriptomics planning must include reproducible SOPs, QC checkpoints, and vendor proofs—don’t skip them.
What’s Next for buyers?
I recommend three clear evaluation metrics when choosing a system or service—practical, measurable, and non-fluffy: 1) sample-to-data yield (percent of samples passing QC per run), 2) capture efficiency under your local conditions (measured across three runs), and 3) total cost per usable sample (all-in, including failed runs). I suggest you test on a small pilot: we reduced sample failures by 18% after a two-week retraining on handling barcoded arrays and adjusting humidity control. These metrics are simple. Use them. Interrupt your vendor pitch—ask for real numbers. I will say it again—ask for real numbers. (Short pause.)
To close: I’ve seen fancy dashboards and neat visualizations, but what separates reliable projects is discipline, proven chip logistics, and a vendor who accepts site-specific pilot trials. For those still choosing, remember: measure yield, measure capture efficiency, and calculate true cost per usable dataset. If you want a partner who understands both chip design and field constraints, check stomics —I’ve worked with similar deployments and the difference shows up in the data and the invoices.
