Introduction — a short scene, a fact, a question
I once waited twenty minutes at a station while the screen blinked and the app refreshed—frustrating, right? Soon after that day I started paying attention to how often drivers hit delays, and I saw numbers that don’t sit well with me: many sites report 10–25% downtime on public chargers. An all-in-one charging station promises to cut that downtime and simplify operations, but does it really deliver on the promise? (Let’s walk through this together.)
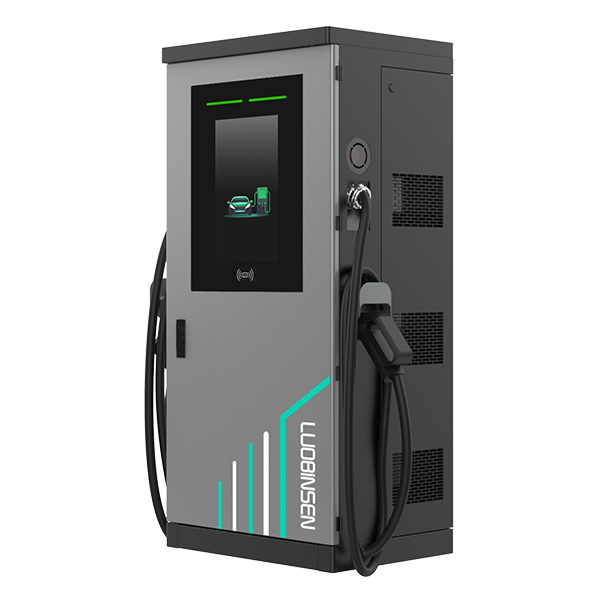
I teach teams and talk to operators; I want this to be practical. Imagine a busy strip mall where three EVs need a charge in an hour. How do you keep the queue moving and the business happy? I’ll show you what I’ve learned about reliability, throughput, and operator pain points—using clear terms like DC fast charging and power converters so we stay concrete. We’ll look at where typical setups fail and where smart, integrated solutions can help. Ready to dig in? The next section breaks down the hidden cracks in current systems and why many drivers still leave unhappy.
Part 2 — Where the old fixes fall short (technical breakdown)
dc electric vehicle charger setups were supposed to be simple: slap a unit by the curb, connect power, and let drivers in. But reality is messier. Many installations rely on legacy power converters and fragmented communication protocols that make monitoring spotty. The result: intermittent failures, slow fault diagnosis, and poor utilization of available grid capacity. I’ve audited sites where a single failed module knocked out a bank of stalls—because components weren’t designed to isolate faults quickly. Look, it’s simpler than you think to imagine the domino effect here.
Technical terms matter because they point to real fixes. Edge computing nodes at the charger would handle local decisions, reducing cloud chatter and enabling faster load balancing. But older stations lack edge logic. Also, billing and authentication often rely on clumsy middleware. That creates wait time, user confusion, and lost revenue. I don’t like throwing around vague critiques—I prefer concrete ones. So when I say the traditional approach mismanages both hardware redundancy and software orchestration, I mean it: redundancy is often cosmetic, and orchestration is manual. — funny how that works, right?
So what’s the core user pain?
The core is predictable: drivers want uptime, speed, and simple payments. Operators want predictable load and easy maintenance. When either side loses confidence, adoption slows. That mismatch is where many projects fail before they scale.
Part 3 — New principles and a forward-looking view
Now let’s shift forward. I want to explain a few new technology principles that actually change outcomes for drivers and operators. First, modular all-in-one units with scalable power converters let sites grow without major rewiring. Second, local intelligence—edge computing nodes—can make split-second decisions about current sharing and thermal limits, which preserves uptime. Third, unified communication stacks reduce protocol translation errors and speed diagnostics. These ideas aren’t pie-in-the-sky; they’re practical design choices that an ev charging provider can implement today to shorten downtime and improve revenue recovery.
In practice, I’ve seen pilot sites adopt these principles and cut mean time to repair in half. They combined predictive alerts with remote firmware updates, and — who knew — that small change kept chargers online much longer. There’s also an operational wrinkle: training. If staff don’t trust remote diagnostics, they’ll still call a tech for every alert. So the human side matters as much as the tech. I say this because I’ve watched teams adapt and then push the systems further. What’s next is combining better hardware, smarter software, and clearer operator workflows to scale quickly.
What to look for
When you evaluate options, I recommend three metrics to guide your choice: availability rate (measured uptime over 30–90 days), serviceability (time and steps to isolate and replace failed modules), and interoperability (how many protocols and vendors the unit supports). These are measurable, and they reveal how the solution behaves in real life—not just on paper. If a vendor can’t produce solid numbers here, be skeptical.
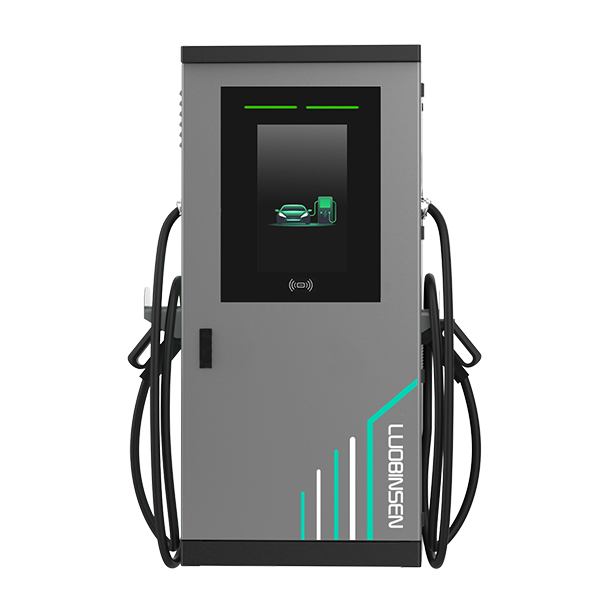
To close, I’ll be frank: I believe the all-in-one approach is the right direction when it’s done with modular hardware, edge intelligence, and clear operator workflows. It reduces frustration and helps sites scale. If you’re comparing systems, use the three metrics above and ask for field data. I trust the teams making practical improvements—and when they deliver, it shows in uptime, cash flow, and driver satisfaction. For further reference and products that follow these principles, see Luobisnen.
